Two-thirds of office professionals have used AI at work believing it broke company policy. A stricter policy is not the fix.
Your confidential material is already going into consumer AI tools, and the people sending it are not being careless. They are doing their jobs with the best instrument available to them, which is the problem.
What the numbers say
A survey of 1,250 office professionals — conducted by Wakefield Research in April 2026, at companies with at least $500 million in annual revenue, and deliberately excluding IT and technology roles — found:
| 66% | used AI at work despite believing it was not permitted under company policy |
| 43% | entered work-related correspondence into public AI tools |
| 34% | entered customer data |
| 31% | input financial information or disclosed confidential documents |
| 39% | would use AI without disclosing it |
One caveat we will state rather than let you discover: that survey covers Australia, Japan, the UK and the United States. It does not cover India. We are not going to convert its percentages into an Indian statistic, because we would be making it up. Read it as evidence of the pattern in comparable large enterprises — which is what it is, and which is enough.
What it looks like when it happens
In May 2023, Samsung Electronics restricted employee use of generative AI tools after three separate incidents inside roughly twenty days at a single division.
An engineer pasted in proprietary source code while debugging. Another transcribed a recorded internal meeting and pasted the transcript in to generate notes. A third used it to optimise a chip test sequence.
Read that list again, because the detail that matters is easy to miss: all three were ordinary work, performed competently. Nobody was careless. Nobody was malicious. Nobody was circumventing a control for personal gain. Three capable engineers reached for the fastest available tool to do the thing they were employed to do.
That is what shadow AI is. It is not a security failure in the usual sense. It is a productivity decision made by someone who does not have the full picture of the risk and does not have a sanctioned alternative that works as well.
Why policy does not fix it
The instinctive response is governance: write the policy, run the training, block the domains. Each of these fails, and the survey shows how.
66% used AI believing it was already against policy. At organisations with more than 1,500 employees, that figure rises to 72%. The policy exists. People are aware of it. They use the tools anyway, because a policy competes with a deadline and loses.
89% of people using AI for their job adopted it outside work first. By the time the question reaches your governance committee, your staff have been using these tools for months in their own lives, have formed a view of how useful they are, and are being asked to give up something that already works.
39% would use AI without disclosing it — 47% at companies above $1 billion in revenue. So enforcement pushes usage underground rather than eliminating it, which is strictly worse: you lose the ability to see what is happening while the material keeps flowing.
Blocking domains fails for the simplest reason of all. The device in their pocket is not on your network.
The uncomfortable inversion: 72% of respondents believe they understand AI use better than their own company's AI management team. Whether or not that is true, it is what the people making the daily decisions believe — and it predicts how much weight your policy actually carries.
Smaller organisations are more exposed, not less
The assumption that this is a large-enterprise problem is backwards. Among the same respondents, 40% of staff at companies with fewer than 1,500 employees entered customer data into public AI tools, against 27% at larger companies.
The reason is structural. Smaller organisations have fewer sanctioned tools, less procurement capacity, thinner IT functions, and correspondingly more individual latitude. The same qualities that make them fast make them porous.
What the risk actually is — stated precisely
We are going to be careful here, because this argument is routinely overstated and the overstatement is what makes security teams tune it out.
Frontier AI providers contract not to train on enterprise data, and there is no reason to believe they violate those contracts. That is not the exposure.
The exposure is that material entering a consumer tool through an individual account is outside your governance entirely. You do not know what was sent. You have no record of it. It sits under consumer terms rather than your negotiated enterprise agreement, subject to that provider's retention schedule, their sub-processors, and their jurisdiction. You cannot answer a regulator's question about it, you cannot include it in a breach assessment, and you cannot delete it, because you do not know it exists.
The problem is not that your provider is untrustworthy. The problem is that nobody in your organisation can tell you what left the building.
What actually removes the incentive
If people use the consumer tool because it is the best instrument available, then the only durable fix is to make the sanctioned instrument better at their actual job.
That is a higher bar than most internal AI deployments clear, and it is worth being specific about what it means:
It has to know things the consumer tool cannot. This is the one advantage that is structurally unavailable to a public chatbot: your contracts, your tickets, your policies, your history. A tool that can answer "what did we agree with this supplier about price escalation" from the actual agreement is doing something ChatGPT categorically cannot, no matter how capable the underlying model is. That asymmetry is the entire basis of the sanctioned option winning.
It has to be fast. If the internal tool takes eight seconds and the consumer one takes two, people will use the consumer one for anything that isn't obviously sensitive — and their judgement about what counts as sensitive is not your judgement.
It has to be where the work is. A separate portal requiring a separate login loses to a browser tab that is already open. Meet people in the tools they are already in.
It must not require permission. Every approval step is a reason to route around it. If using the sanctioned tool is more friction than not using it, you have built a control, not an alternative.
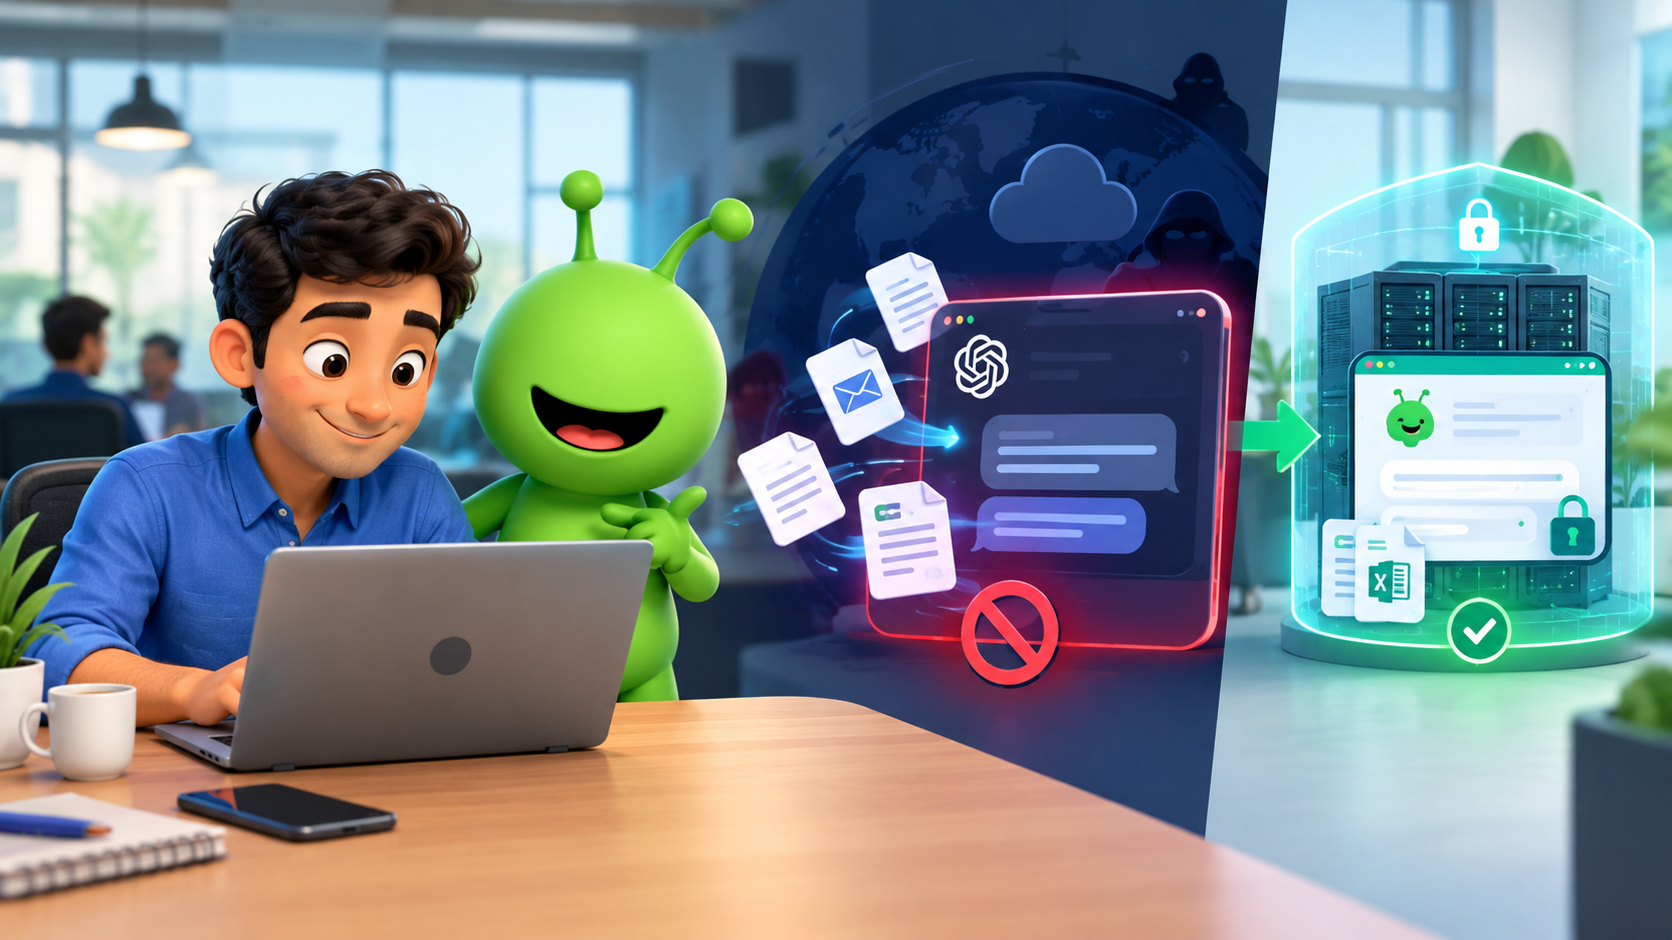
And the sensitive path has to be enforced in code. A rule saying "don't put client data in the external tool" is not a control — it is the same policy that 66% of respondents already ignore. A model registry and a privacy filter that make the sensitive path physically unable to reach an external endpoint is a control. The difference is whether the guarantee survives someone being in a hurry.
The honest limits
This does not eliminate the risk, and we are not going to claim it does.
Someone can still use their phone. Someone can still decide the internal tool is inconvenient for one particular task. A sanctioned alternative changes the economics of the choice; it does not remove the choice.
What it does change is the shape of the residual problem. Instead of everyone routing around a policy that competes with their deadline, you get a small number of people making a deliberate exception — which is a governance problem of a size you can actually manage, and which your monitoring can actually see.
That is a realistic goal. Zero shadow AI is not.
What to do this week
Four things, in order, none of which require buying anything:
- Measure before you legislate. Find out what is actually being used and for what. Ask, in a way that does not punish honest answers — the survey above suggests that punitive framing produces concealment rather than compliance.
- Find the two or three workflows driving most of it. Shadow AI is not uniform. It clusters around a handful of genuinely painful tasks — usually drafting, summarising long documents, and explaining something unfamiliar.
- Sanction something immediately, even if it is imperfect. An enterprise agreement with a frontier provider, with your own terms and your own logging, is dramatically better than individual consumer accounts and can be in place in days. It is not the end state, but it stops the bleeding.
- Then decide what needs to be internal. The workflows that touch your most sensitive material — and only those — are the ones that justify an architecture where the data physically cannot leave.
That last step is where we work. The first three you should do regardless of whether you ever talk to us, and they are worth more in the first month than any procurement decision.
Sources. Shadow AI Survey conducted by Wakefield Research, 9–20 April 2026, n=1,250 office professionals at organisations with $500M+ annual revenue, excluding IT and technology roles, across Australia, Japan, the UK and the US; published by PagerDuty. Samsung incidents as reported by Bloomberg and Forbes, May 2023.
Want to know which of your workflows genuinely need to stay internal? A one-day Discovery Sprint produces a written recommendation — including the recommendation that a workflow does not need on-premise infrastructure, where that is the answer.