Three ways to deploy enterprise AI
Cloud API, hybrid, or on-premise — what each actually is, what it costs at real volumes, and the numbers that decide.
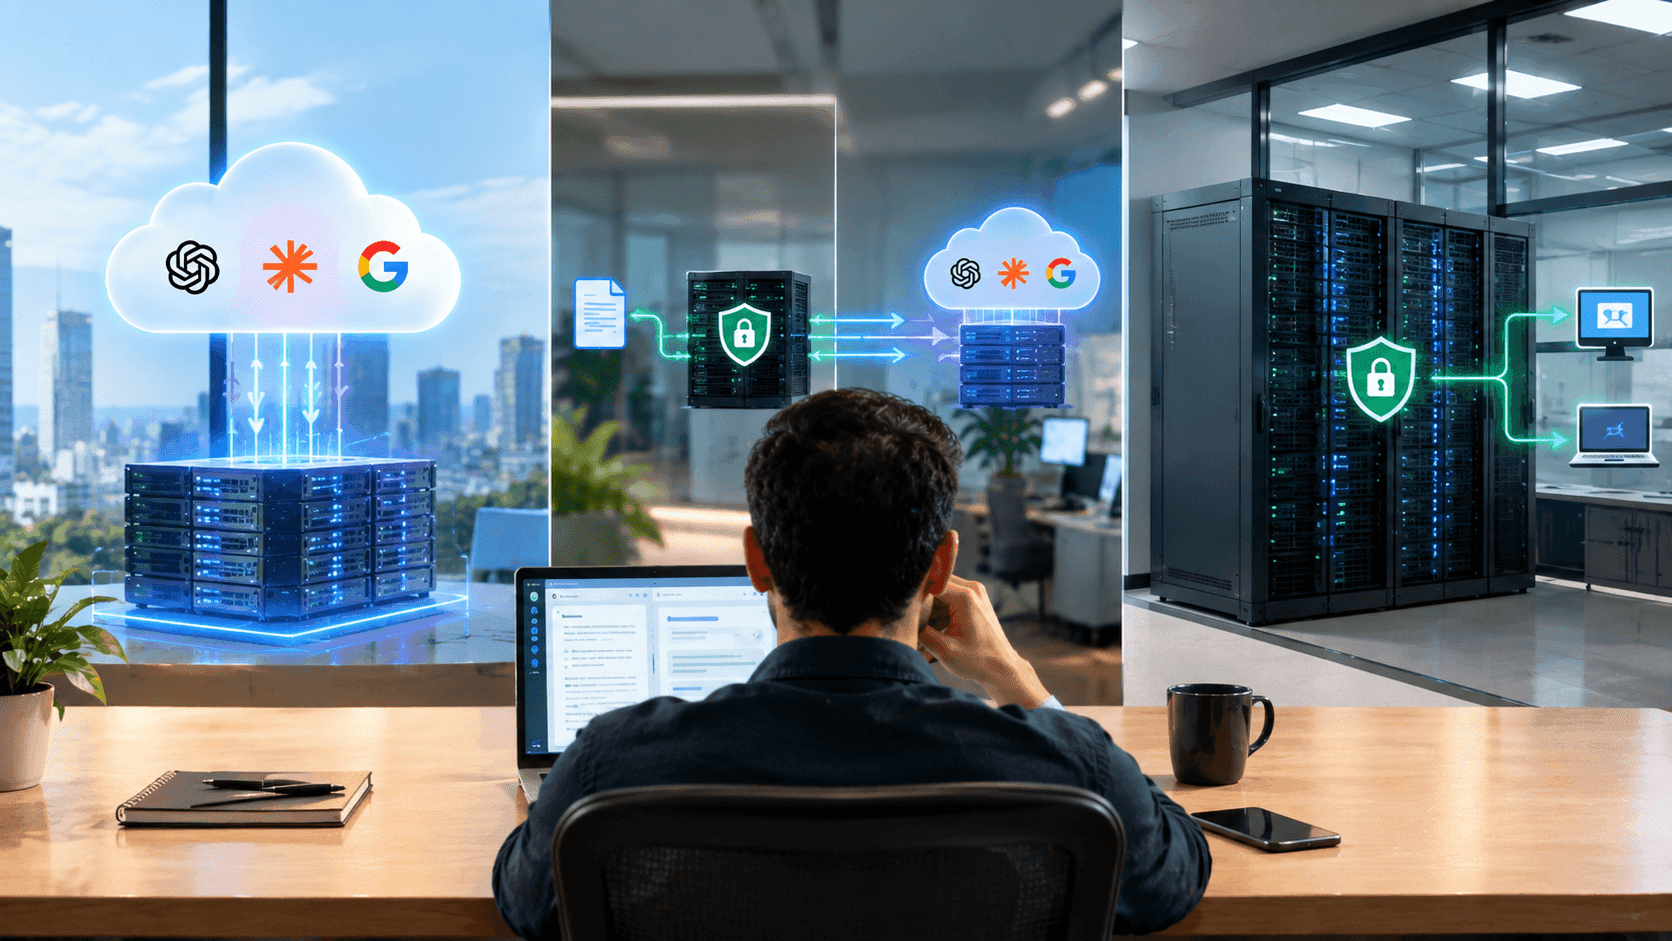
There are three ways to put AI in front of your organisation: rent it over an API, split it across a hybrid boundary, or own it on your own infrastructure. Each is the right answer for somebody. The numbers decide for whom.
The three approaches, plainly
1 — Cloud API. Your users' prompts and documents travel to a provider's infrastructure; answers travel back. Zero capex, immediate start, per-token pricing. The provider holds the working context, and your governance is a contract: retention, residency and training-use promises you must trust and cannot verify from your side of the wire.
2 — Hybrid. The stack is split. Retrieval, redaction and the privacy rail run on your infrastructure; some or all inference is routed out — either to a frontier API for designated task classes, or to rented GPU capacity. Done properly this is policy-routed: sensitive material is grounded and answered locally, and only what policy explicitly permits crosses the boundary, with every routing decision logged.
3 — On-premise. The entire request path — privacy filter, retrieval,
inference, validation, audit — runs inside your building on hardware you own.
Open-weight models served locally; no egress path to any external provider. In
our fail-closed on_prem_required mode, a misconfiguration refuses rather
than transmits.
What each costs — with the volumes attached
Cost claims without volumes are how this decision goes wrong.
At low volume, the cloud API wins. If your volume is low, a metered cloud API can cost less than a GPU server, a licence and a yearly service. We work that out on your numbers on the scoping call, and we say so when the answer is no.
At sustained volume, ownership crosses over. Rented cloud models are metered: every new user adds to the bill. Owning your AI costs a one-time site licence of ₹50–90 L (₹35 L for a platform-only site) plus a managed service of ₹16–18 L a year, with hardware passed through at cost — indicatively ≈₹12.5–16 L per 96 GB GPU card, or ₹68–80 L per 4-GPU server, ex-GST. The cost per query falls as use grows.
Running costs are part of the plan. A 4-GPU server draws about 3.5 kW and needs about 1 TR of cooling and a 6 kVA UPS; site power and cooling are yours.
What moves the line
Three things drag the crossover earlier, and none of them is hardware price:
Context length. Longer contexts mean more tokens per query at the same query count. Retrieval-augmented work runs long contexts by construction.
Premium model tiers. API pricing scales with the model tier; owned hardware does not care which open-weight model it serves.
Agentic workloads. An agent that chains several model calls per user action multiplies token throughput without multiplying your capex.
If your roadmap includes retrieval over your own documents and agents that act, your token curve is steeper than your query curve — and the crossover is closer than a per-query estimate suggests.
Hybrid, honestly
Hybrid is genuinely right where workloads split cleanly: grounded, sensitive work at volume on your side; occasional frontier-capability tasks routed out by policy. That is our own default posture — sovereign by default, frontier by choice.
Its honest cost is governance: two surfaces instead of one. You must be able to say, per request, which side of the boundary it ran on and why — which is an audit-record requirement, not a slide. If your team cannot evidence the split, hybrid quietly degrades into the cloud approach with extra steps.
The decision, compressed
| Your situation | Right approach |
|---|---|
| Low volume, little private grounding | Cloud API |
| Sensitive corpus, volume growing, some frontier tasks | Hybrid, policy-routed |
| Sustained volume, regulated or confidential material | On-premise |
Start with the sizing, not the software: query volume, context length, concurrency, and the state of your document estate. Those four numbers make this decision for you — and if they say "don't buy," we will say it too.
Companion pieces: Frontier vs grounded — the wrong axis · The anatomy of an on-premise AI deployment · Operational alpha — the advantage you own
Book an Architecture Consultation
30 minutes. No sales pitch. We map what this paper means for your stack and give you a concrete deployment path.
Your Data. Your Premises. Your AI.